How the three patterns differ by decision
| Dimension | Batch extract | Log-based CDC | Event streaming |
|---|---|---|---|
| What it reads | The source table, through a query on a schedule. | The database transaction log, after an initial snapshot. | Nothing at the source — the application publishes the event. |
| Load on the source | Real, and it competes with production traffic. | Close to none; the log is already being written. | None; the cost moves into the producing application. |
| Typical freshness | Minutes to a day, bounded by source capacity. | Seconds to minutes, bounded by connector and target. | Sub-second to seconds, bounded by the consumer. |
| Deletes | Invisible unless the application soft-deletes and the extract reads the flag. | Captured natively as change events. | Captured if the application publishes a deletion event. |
| Intermediate states | Lost — only the state at extract time is seen. | Preserved; every committed change appears. | Preserved as published. |
| State you must own | None beyond the last successful window. | An offset, plus the snapshot-to-stream handover. | Consumer offsets, partitions and lag. |
| Schema change | Discovered on failure or as a null column. | Arrives as a DDL event the connector may or may not act on. | Can be refused at the boundary by a registry compatibility rule. |
| Replay | Rerun the window against the source, if the source still holds it. | Bounded by log retention; beyond it, resnapshot. | Bounded by topic retention, independent of the source. |
| Skills required | SQL and scheduling. | Database internals, log configuration and connector operations. | Distributed log operations: partitions, consumer groups, lag. |
| Where it breaks first | Source capacity, as frequency rises. | Log retention, during any prolonged outage. | Producer discipline, when payloads change unannounced. |
Start from the freshness each decision genuinely needs
Write down the decision the data serves and how stale it can be before the decision changes. A weekly margin review does not need sub-second data; a card-authorisation check cannot use yesterday's. Freshness is a per-decision requirement that belongs in the data engineering scope rather than in a platform-wide setting, and stating it per decision is what stops an estate from buying streaming for a report nobody reads before Monday. The logistics shipment lifecycle makes this distinction concrete: a carrier status change and the business action it triggers can arrive on different clocks and need separate correction rules.
The common failure is a blanket "real-time" requirement that nobody traced to a decision. It survives because it sounds safe, and it is expensive in a way that does not show up until the second year: every stream needs ordering rules, replay handling, a retention policy and somebody who can reason about consumer lag at two in the morning. A batch job that runs at 04:00 needs a scheduler and a runbook.
The opposite failure is quieter. A team standardises on nightly batch, and a decision that needed hourly data silently degrades into a decision made on instinct, because the number on the screen is known to be old. Nobody escalates it, because no freshness target was ever stated to breach.
- State freshness as a target per data product, with the decision it serves named beside it
- Separate the freshness of arrival from the freshness of the published model — they are different numbers
- Record the cost of being wrong at that staleness, because it is the only thing that justifies the pattern
How batch extraction puts load on the system you are reading
A batch extract is a query against the source, so the source pays for it. A full extract rereads every row each run; a windowed extract reads only rows whose updated timestamp falls in the window, which is cheaper but depends on that column being maintained correctly on every write path. Either way, the read competes with production traffic on the same database.
That competition is the practical limit on batch frequency. Running a full extract hourly against an operational database is usually not a scheduling decision but a capacity decision, and it is made by whoever owns that database rather than by the data team. This is why batch frequency so often stalls at nightly: not because nightly was right, but because it was the only window with spare capacity.
Windowed extraction has a specific correctness trap. It trusts an `updated_at` column, and that column is only as reliable as the least careful write path in the application — a bulk update, a migration script or a trigger that bypasses the ORM will move rows without moving the timestamp. Those rows are then invisible to every subsequent extract, and the gap does not announce itself.
Deletes are the other gap. A query against the current table cannot see a row that is no longer there. Unless the application soft-deletes and the extract reads the tombstone, deleted records simply persist in the warehouse indefinitely, quietly inflating every count built on them.
Why log-based CDC reduces source-system load
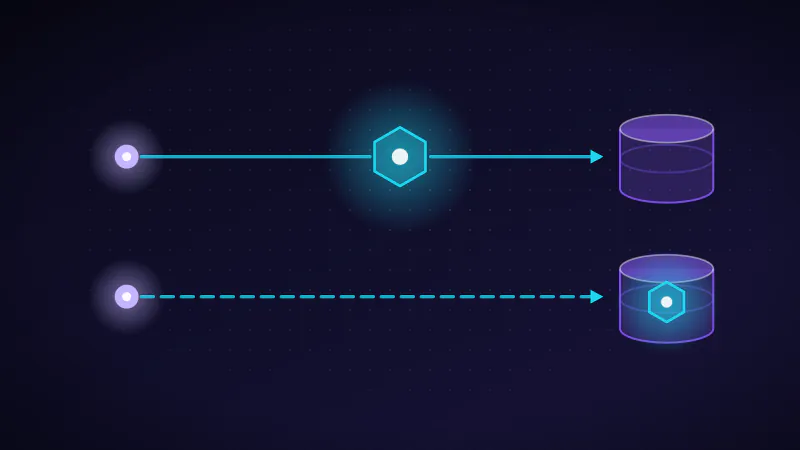
Log-based change data capture reads the database's own transaction log instead of querying tables, so the source does almost no extra work to serve it. The log is already being written for durability and replication; CDC attaches to that existing stream. Debezium's connectors work this way, reading the MySQL binlog or a PostgreSQL logical replication slot instead of issuing SELECTs.
AWS Database Migration Service takes the same approach with engine-specific mechanisms: Oracle LogMiner or the binary reader API reading redo logs by system change number, SQL Server's transaction log read through `fn_dblog()` by log sequence number, MySQL row-based binlogs, and PostgreSQL logical replication slots. Snowflake's streams apply the idea inside the platform, storing an offset against a source object instead of a copy of its data.
The consequence that matters commercially is that CDC changes who has to approve the ingestion. Because the read cost on the source is close to nothing, the conversation with the DBA becomes about log retention and supplemental logging rather than about query capacity. That is usually a much easier conversation, and it is frequently the reason a stalled ingestion project moves again.
CDC also captures deletes natively, because a delete is a log event like any other. It captures the intermediate states of a row, too: if a record is updated three times between two batch windows, batch sees only the final state while CDC sees all three. Whether that is a feature or noise depends on whether anyone downstream needs the history, which is a question for the warehouse model rather than for the connector.
- Log retention on the source becomes a hard dependency — if the log ages out before the connector reads it, the gap is unrecoverable without a resnapshot
- Most engines need configuration first: Oracle supplemental logging, MySQL row-level binary logging, a PostgreSQL replication slot
- A replication slot that no consumer is reading will hold write-ahead log on the source until the disk fills, so a stopped connector is an operational incident, not a pause
What CDC costs you that batch does not
CDC moves complexity from the source system into your pipeline. You now own an offset, a snapshot-then-tail lifecycle, and an initial load that has to hand over to the change stream without dropping or duplicating the rows committed during the handover. None of that exists in a batch extract, which starts from nothing every run and is therefore trivially restartable.
The handover is the part teams underestimate. AWS DMS names the shape explicitly — full load plus CDC, or CDC-only from a native start point such as an SCN, LSN or binlog position — and warns that open transactions started before the chosen start point and committed after it are missed unless the task is configured to account for them. That is a correctness hole with no visible symptom: the rows are simply absent.
Then there is staleness of the change stream itself. Snowflake streams go stale when their offset falls outside the source table's data retention period, and the platform extends retention for unconsumed streams specifically to reduce that risk. The general principle holds everywhere: a CDC consumer that stops for longer than the log's retention window cannot resume, it can only resnapshot.
Finally, CDC gives you at-least-once delivery in practice, not exactly-once. The landing side has to be idempotent regardless. That is the same requirement streaming brings, and it is the reason the two patterns are closer to each other operationally than either is to batch.
When event streaming is the right answer
Event streaming is the right pattern when the event itself is the fact, instead of a side effect of a row changing. A click, a sensor reading, a page view or a payment authorisation has no authoritative row in an operational table to read later — it exists only as it happens. For those, streaming is not a faster ingestion method, it is the only lossless one.
It is also the right answer when many consumers need the same events independently. A topic with a retention window lets a new consumer start from the beginning of that window without asking the producer for anything, which is a genuinely different capability from either batch or CDC. Confluent's documentation describes the delivery guarantees precisely: at-most-once loses messages on failure, at-least-once may deliver duplicates, and exactly-once requires the idempotent producer plus transactional coordination with the output system.
The important qualification is that these guarantees describe the transport. An exactly-once transport writing into a non-idempotent load step still produces duplicates. Whatever the pattern, the landing contract decides correctness.
When Kafka is not necessary
Kafka is not necessary when there is exactly one consumer, the data already exists as rows in a database, and no replay requirement extends beyond what the warehouse can reproduce. In that situation a broker adds a durable distributed log, a partition and ordering model, a consumer-group protocol and an operational surface — to solve a problem that a CDC connector writing directly to the target already solves.
This matters because a broker is usually introduced as infrastructure rather than as a decision, and it is very hard to remove once three teams depend on it. The honest test is whether you need a durable, replayable, multi-consumer log as a first-class asset. If you do, that is a real architectural need and a broker is the right tool. If what you actually need is "get these row changes into the warehouse within five minutes", CDC into the platform is a smaller system with fewer ways to fail.
The same reasoning applies in reverse. Teams sometimes avoid streaming when the producing application is already emitting events for other reasons, and reconstruct those events by polling a database table the application writes as a side effect — which is more machinery, not less, and loses every event that does not survive as a row.
| Dimension | A broker is likely justified | A broker is likely unnecessary |
|---|---|---|
| Where the fact lives | The event is the fact and is not durably stored anywhere else. | The fact is a row in an operational database that can be read later. |
| Consumers | Several independent consumers need the same events at their own pace. | One pipeline consumes the data, into one target. |
| Replay | Replay from an arbitrary point in a retention window is a stated requirement. | Replay means rerunning a transformation the warehouse can already reproduce. |
| Ordering | Per-key ordering has business meaning and must be preserved end to end. | Final state is what matters; intermediate states are not read. |
| Who operates it | A team exists that can own partitions, lag, retention and rebalancing. | Nobody currently on call can reason about consumer lag. |
| Coupling | Decoupling producers from consumers is the actual goal. | The only coupling problem is that the extract query is too heavy. |
The landing contract all three patterns share
Whatever produces the data, the landing step needs the same four decisions: an idempotency key that makes a rerun safe, an ordering rule that says how two versions of the same record are resolved, a late-arrival policy that says what happens to data for a period already published, and a replay window that says how far back you can rebuild. Getting these right matters more than the pattern above them.
Idempotency is the load-bearing one. At-least-once delivery is the realistic default for CDC and for streaming, and batch reruns happen after every failed night, so every one of the three patterns will at some point present the same record twice. A load that is idempotent on a natural key turns that from an incident into a non-event.
The late-arrival policy is the one most often left implicit, and it is where reported numbers quietly diverge. If a record for Tuesday arrives on Thursday, does Tuesday's published figure change? Both answers are defensible. Only one of them can be true in a given model, and if it is not written down, two consumers will assume differently and produce two numbers for one question.
- Idempotency key: the natural key plus a version or sequence, never the arrival time
- Ordering rule: source commit order, source timestamp, or arrival order — pick one and state it
- Late-arrival policy: restate the period, hold it in a correction table, or reject beyond a window
- Replay window: how far back the raw layer can rebuild the published model without the source
How each pattern fails, and what the failure looks like
The three patterns fail in characteristically different ways, and the difference matters because two of them fail silently. Batch fails loudly when a job errors and silently when a windowed extract misses rows. CDC fails loudly when a connector stops and silently when the log ages out. Streaming fails loudly on consumer lag and silently when a producer changes an event shape nobody was validating.
Designing for detection is therefore pattern-specific. A batch pipeline needs a reconciliation count against the source, because nothing else will reveal rows an `updated_at` filter skipped. A CDC pipeline needs monitoring on replication-slot lag and log retention headroom, because the symptom appears at the source before it appears in your data. A streaming pipeline needs schema validation at the boundary, because the producer can change the payload without any contact with you at all.
| Dimension | How it presents | Control that catches it |
|---|---|---|
| Batch: job failure | Loud. The run errors and the target is simply not updated. | Freshness check on the target, alerting to a named responder. |
| Batch: missed rows | Silent. Rows updated without moving `updated_at` are never extracted. | Periodic full reconciliation of counts and key sets against the source. |
| Batch: invisible deletes | Silent. Deleted rows persist in the target and inflate every count. | Full key-set comparison, or a soft-delete flag the extract reads. |
| CDC: connector stopped | Loud at first, then dangerous. Lag grows; on some engines the source retains log until disk pressure. | Alert on replication lag and on log-retention headroom, not just on task status. |
| CDC: log aged out | Silent until resume. The offset is outside retention and the gap cannot be recovered. | Retention alarm sized to the longest tolerable outage, plus a rehearsed resnapshot. |
| CDC: snapshot handover | Silent. Transactions open across the start point are absent with no error. | Explicit start-point configuration and a post-load reconciliation. |
| Streaming: consumer lag | Loud. Lag rises against the topic and eventually breaches retention. | Lag monitoring with a threshold below the retention window. |
| Streaming: payload change | Silent or loud depending on the reader — often a null column instead of an error. | Schema registry with an enforced compatibility rule at the boundary. |
| All three: duplicate delivery | Silent. Counts and sums inflate; distinct counts do not. | Idempotent load on a natural key, verified by a uniqueness test. |
Schema change propagates differently in each pattern
A batch extract usually discovers a schema change when the load fails or a column arrives as null. CDC surfaces the change as a DDL event in the stream, which the connector may or may not be configured to act on. Streaming is the only one of the three where the change can be refused before it reaches you, because a schema registry sits between the producer and the topic.
That is a real argument for streaming that has nothing to do with latency. Confluent's schema registry enforces a named compatibility rule — BACKWARD lets a consumer on the new schema read data written with the old one and requires consumers to be upgraded first; FORWARD is the reverse and requires producers first; FULL permits only optional field additions and removals and lets both sides move independently. Setting the rule is the point, because it converts an ambiguous "don't break things" norm into something a build can fail on — which is the whole argument for data contracts at a team boundary.
The same instinct can be applied without a broker. dbt model contracts enforce column names and data types at build time and fail the run when a contracted column is removed or its type changes. The mechanism differs; the discipline is identical, and it belongs wherever data crosses a team boundary.
A worked example: one order table, three consumers
Take a single orders table feeding three decisions: a monthly margin review, a next-day replenishment run, and a fraud check at authorisation time. The correct answer is not one pattern for the table. It is a nightly batch extract for margin, log-based CDC for replenishment, and an application event for fraud — three patterns over one source, each sized to a decision.
Margin is settled monthly and reviewed against a closed period, so it needs a stable snapshot more than a fresh one, and a nightly windowed extract with a full monthly reconciliation is both sufficient and cheap. Replenishment runs every few hours and is sensitive to cancellations, so it needs deletes and it needs the source untouched during trading hours — which is precisely the CDC case. Fraud has to decide before the authorisation completes, so nothing that reads the table afterwards can serve it; the application must emit the event.
What makes this arrangement work is not the three patterns but the one contract underneath them. All three land against the same idempotency key and the same ordering rule, so the margin figure, the replenishment input and the fraud feature all resolve the same order to the same record. Where estates get this wrong, they do not get three latencies — they get three versions of an order.
What this guide does not settle
This guide compares patterns, not products, and it does not tell you which connector, broker or managed service to buy. It also assumes a relational source. Ingestion from SaaS APIs, files dropped on object storage and third-party feeds has a different shape, and the wider question of where transformation should run is answered separately: no transaction log to read, rate limits instead of capacity contention, and vendor-defined pagination semantics that constrain what incremental even means.
Two further limits are worth stating. First, the cost comparison here is structural rather than numeric — where the money goes, not how much. Any figure would depend on your volumes, platform and contract, and a number quoted without those is worse than no number. Second, this guide treats correctness at the landing boundary and stops there; what happens to late-arriving data inside a published model is a modelling decision that belongs with the medallion layer resolving it, not with ingestion.
Separate a row change from a business event.
Delivery pattern and business meaning are separate decisions. In this hypothetical orders system, a row update might reflect a shipping-address correction, an order acceptance or an internal recalculation. A consumer that needs accepted-order events cannot assume every captured database change represents that transition.
Scope and assumptions: Document the source's transaction and application semantics before choosing an interface. Connector metadata can describe changes and transaction boundaries; it does not independently define the business event. The examples below describe required evidence rather than a connector configuration.
| Dimension | Meaning to preserve | Evidence before choosing a pattern |
|---|---|---|
| Current state | A reporting consumer may need the latest accepted order state at a defined cutoff, rather than every intermediate update. | Identify the cutoff and required deletions or corrections. Check whether the chosen batch or change feed can reconstruct that state without interpreting every update as a new sale. |
| Business event | A fulfilment consumer needs a defined transition, such as order accepted, with a stable identity and the context needed to act. | Ask the application owner which transition creates the fact and where it is recorded. Distinguish a change in storage from a command or event intended for another application. |
| Transaction group | An order and its lines may change together. Decide whether the consumer needs a consistent transaction group or can accept partial arrival. | Inspect the actual connector's boundary metadata and source coverage. Debezium's PostgreSQL connector can enrich events with transaction metadata when enabled; that does not by itself implement consumer-side assembly. |
| Delete meaning | Removing a database row is not automatically a cancellation, refund or request to reverse a downstream action. | Record why deletions occur and where business reversals are represented. Test the intended consumer outcome against both a technical cleanup and an actual cancellation. |
| History needed | A latest-state copy cannot establish every transition that occurred between observations. Decide whether the consumer needs state, transition history or both. | Use a fixture that changes and changes back between two extracts. If the missing intermediate transition matters, select an interface that preserves it rather than shortening a polling interval without proof. |
At narrow widths, scroll the worksheet to read every column. With the table focused, use the arrow keys to scroll.
Worked decision: an address correction updates an accepted order's database row. An analytical state consumer may need that correction; a fulfilment consumer should not infer a second acceptance from it. Define the event contract or transition logic with the application owner, then evaluate batch, CDC or application events against that requirement.
- Keep source-event identity separate from business-event identity. A database position can help identify a captured change without explaining what business action that change authorizes.
- Where transaction metadata is used, record when capture began and which history is available. Do not reconstruct a missing business event from an undocumented assumption about a connector field.
If a consumer needs timely business events and a correction path, connect the interface decision to the real-time streaming consumer requirements before choosing a broker or processing engine.
Official references for this example:
Questions and trade-offs
Question
Can we run more than one pattern against the same source?
Yes, and for a source serving decisions with different freshness needs it is usually the right answer. The condition is that every path lands against the same idempotency key and the same ordering rule. Without that, the patterns do not give you three latencies — they give you three versions of the same record, and reconciling them later is far more expensive than agreeing the key now.
Question
Is CDC always better than batch if the source can support it?
No. CDC is less intrusive to the source and captures deletes, but it moves real operational complexity into your pipeline: an offset, a snapshot handover, and a hard dependency on log retention that turns a long outage into an unrecoverable gap. Where nightly freshness genuinely serves the decision and the source has capacity, batch is the smaller system, and a smaller system is easier to keep correct.