How the two tools divide the work
| Dimension | Airflow (orchestration) | dbt (transformation) |
|---|---|---|
| Primary job | Coordinate tasks across systems on a dependency graph. | Transform data inside the warehouse as versioned models. |
| Lives where | External to the warehouse, alongside other systems. | Inside the data platform. |
| Dependencies | Task-level dependencies across systems and time windows. | Model-level dependencies resolved from the SQL graph. |
| Testing | Task success, SLAs and arrival checks. | Data tests attached to models and sources. |
| Backfill model | Replay task runs for a bounded window. | Rebuild selected models for a date range. |
| Failure surface | Connections, credentials, late sources, task timeouts. | Model logic, upstream data quality, warehouse cost. |
| Who owns it | The team operating ingest and cross-system movement. | The analytics engineering owner of the modelled layer. |
| Limitations | Does not govern transformations or their semantics. | Does not schedule or move data between systems. |
Scheduling versus orchestration
A scheduler answers one question: when should this job run? An orchestrator answers several: what must complete first, what happens when it does not, how is a failed run replayed, and who is accountable for the outcome. The difference shows up on the day a source arrives late and time-based dependencies quietly produce an incomplete dataset.
Where Airflow fits
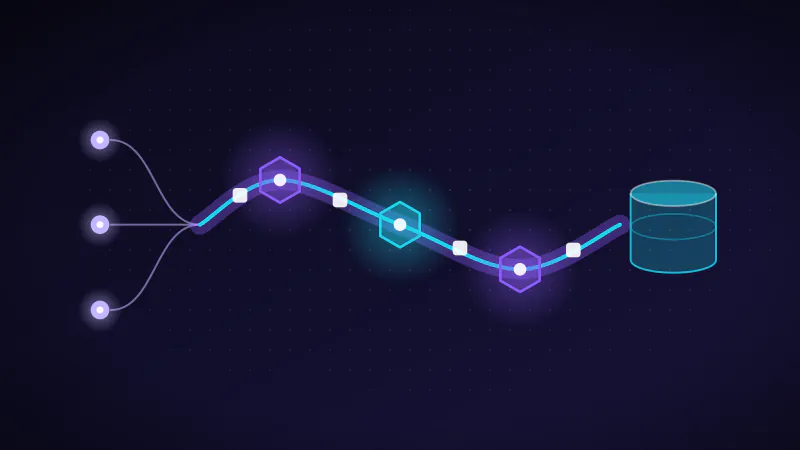
Airflow coordinates tasks across systems: extracting from a source, waiting for a file, calling a warehouse load, triggering a transformation and confirming a downstream consumer. Its value is the dependency graph, retry policy, alerting and the operational visibility of what ran, when, and with what outcome.
Airflow describes work as DAGs written in Python. Sensors wait for a condition such as a file landing; retries and timeouts are set per task; and data-aware scheduling lets one DAG run when another has produced the data it needs, without a fixed clock time.
Where dbt fits
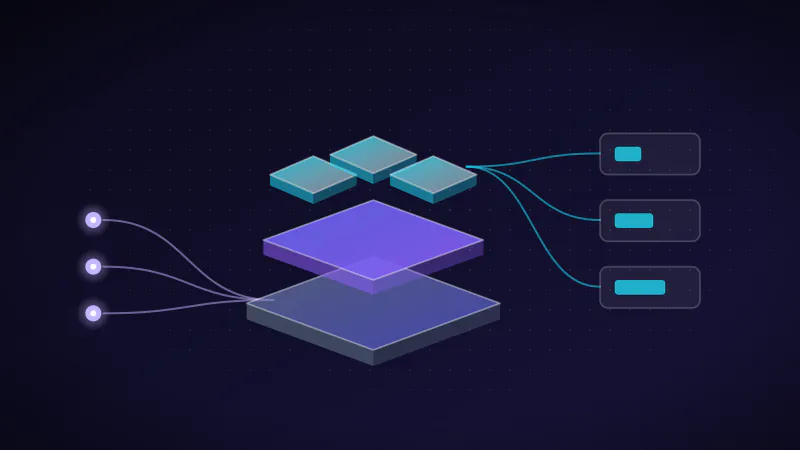
dbt transforms data inside the warehouse, expressing models as versioned SQL with tests, documentation and lineage. It brings software practice to the transformation layer instead of the movement layer, which is why it pairs well with an orchestrator that handles ingestion timing and cross-system tasks.
dbt projects are commonly layered as staging models that clean and rename source columns, intermediate models that apply joins and logic, and marts that serve consumers. Source freshness checks fail a run when upstream data is late, and state-based selection rebuilds only the models that changed plus everything downstream of them.
- Models versioned and reviewed like code
- Tests attached to models, not to the schedule
- Lineage generated from the dependency graph
Dependencies must be declared, not implied
Undeclared interface promises and implicit dependencies — a job that assumes another finished a minute earlier — are the most common cause of intermittent data defects. Declare them in the orchestrator or in the model graph so the platform, not a timetable, decides order. When a dependency is genuinely time-based, state that as a decision with a reason.
Backfills, retries and recovery
Every production pipeline needs an answer for replay. Decide how a failed run is retried without duplicating data, how a backfill is scoped and rate-limited against source systems, and how corrected data reaches consumers. Rehearse it: a recovery path that has never been used is a plan, not a capability.
Illustrative example · hypothetical organisation
Worked example: a late source, handled
Take a hypothetical nightly pipeline where a payment provider's settlement file normally lands by 02:00.
With a schedule alone, transformations start at 03:00 whether or not the file arrived, and the morning dashboard shows a short day. With orchestration, a sensor waits for the file, the load runs when it lands, and dbt starts only after the load succeeds.
If the file has not arrived by 05:00, the DAG alerts the payments data owner, not a shared channel, and the dashboard keeps showing the last complete date. When the file finally arrives, that date's run is cleared and re-run, and dbt rebuilds the affected models and their downstream marts.
Ownership and alert routing
Orchestration makes failure visible, which is useful only if someone is responsible. Map each pipeline to an owner, route alerts by business impact rather than by error type, and review recurring incidents for a cause instead of closing them. A shared inbox with no owner turns observability into noise.
Questions and trade-offs
Question
Do we need Airflow if we use dbt?
Often yes, unless every input already arrives inside the warehouse on a reliable schedule. dbt builds and tests models; it does not decide when to fetch a file, wait for a source system or coordinate a task that lives outside the warehouse. Orchestration covers that boundary.
Question
Can a scheduler alone be enough?
For a small number of simple daily pipelines with stable source timing and manual oversight, maybe. It stops being enough when dependencies are cross-system, when backfills need scoping, or when failures need to reach a specific owner quickly — which is most production estates.
Question
Are there alternatives to Airflow?
Yes. Dagster and Prefect are common open-source orchestrators, and managed services such as AWS Step Functions, Azure Data Factory and Databricks Workflows cover many cases. The requirements do not change with the tool: declared dependencies, retries, backfills, alert routing and an owner.